Iovanny Olguín Ávila
Posts
Nemotron Labs Dory 1.0 4B on an 8 GB GPU: What Fits and What Does Not
Nemotron Labs Dory 1.0 4B fits an 8 GB GPU in Q5_K_M or FP4 formats, but BF16 does not. Weight sizes, loop trade-offs and what...
Local AI Hardware in the DRAM Crunch: Buy Now or Wait? (DGX Spark vs Strix Halo vs Mac Studio vs a GPU Rig)
Local AI hardware: DGX Spark is $4,699, 128GB Strix Halo boxes sit near $3,500, and the new Mac Studio starts at $2,499. Who should buy,...
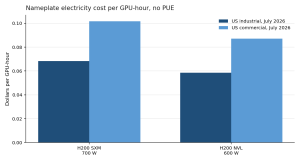
GPU Electricity Cost: What a 700-Watt H200 Adds at July 2026 U.S. Prices
GPU electricity cost at 700 watts is $0.0684 an hour at the July 2026 U.S. industrial price and $0.1017 at the commercial price, before the...
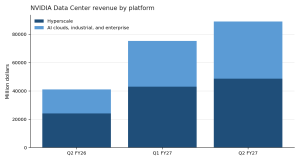
NVIDIA Data Center Revenue in Q2 FY2027: The Split Buyers Should Use
NVIDIA data center revenue was $89.0 billion in Q2 FY2027. Hyperscale grew 13.15% and the other line 25.21%. The mix, recomputed from the 8-K.
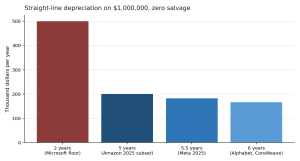
Server Useful Life: What Five AI-Infrastructure 10-Ks Actually Depreciate
Server useful life in five 2025–2026 10-Ks runs from 2 to 6 years. Meta lengthened, Amazon shortened a subset, and the dollar gap is recomputed.
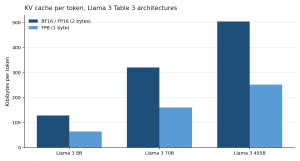
KV Cache Memory: How Many Llama 3 Tokens Fit on One H200
KV cache memory on one H200: Llama 3 70B at 16-bit weights leaves 1.0 GB, about 3,052 tokens. Byte formula, unit trap, and a worked...
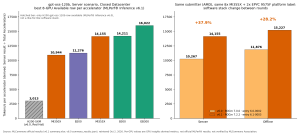
MLPerf® Inference v6.1 Per-GPU Results: The 5.7× Headline, Recomputed for Hardware You Can Buy
Per-GPU recomputation of MLPerf® Inference v6.1: the 5.7× headline is 3.04× for Available hardware, and software moved AMD 37.9%.
Edge AI vs Cloud GPU Inference 2026: The Data Sovereignty and Latency-Cost Framework
A construction-site monitoring system that ships raw video to the cloud for object detection is not primarily an engineering decision in Europe in 2026 —...
Custom AI Silicon vs GPU Rental 2026: When TPU, Trainium, and Maia Beat NVIDIA and AMD
Google will tell you its seventh-generation Ironwood TPU delivers roughly 44% lower total cost of ownership than a comparable GB200 configuration. What Google will not...
vLLM vs SGLang vs TensorRT-LLM 2026: The Enterprise Inference Engine Decision
A platform engineer migrating a production chatbot from vLLM to TensorRT-LLM in early 2026 discovered the throughput gain everyone promised — roughly 13% more tokens...